Last year, Google DeepMind sent gaming stocks tumbling with the reveal of its Genie 3 world model. Since then, world models have become a major focus of AI labs around the world, but Google isn’t resting on its laurels. Researchers have been hard at work on an updated model that improves on the Genie 3 in almost every way. And if you pay Google enough money, you might be able to use Genie 4 in no time.
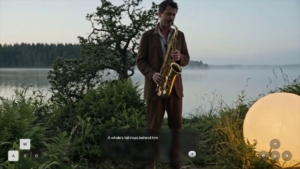
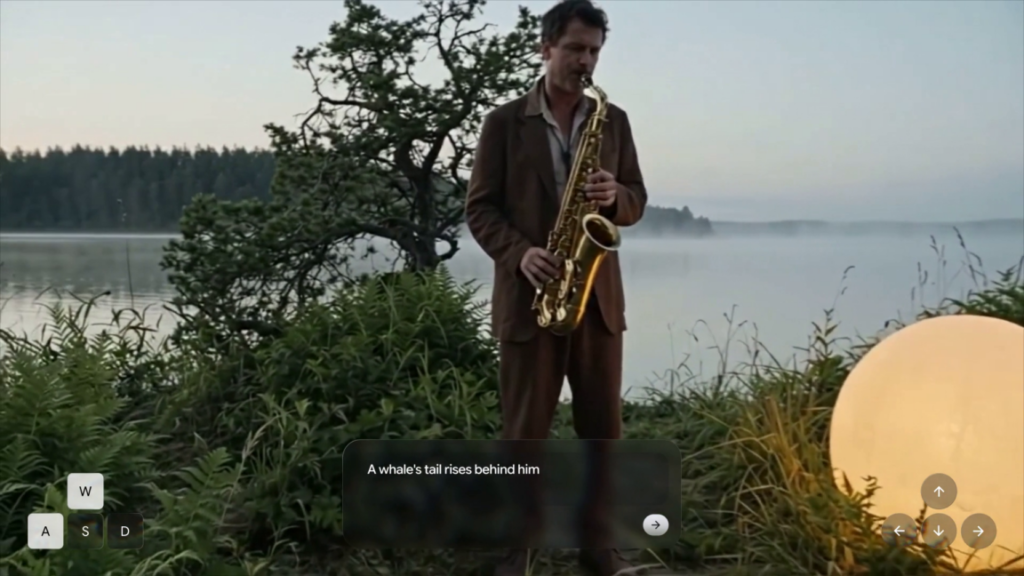
It’s easy to look at the output of Genie 4 and see a video game, which is why Genie 3 caused so much consternation in the gaming industry. However, DeepMind doesn’t think about it that way. According to Google, global models are a key element in the march towards artificial general intelligence (AGI). A world model creates a virtual world, but does not require pre-rendering environments or programming of interactive elements. You simply tell the model what you want and it generates the experience frame by frame in real time as you explore it.
DeepMind says this technology could create infinite training environments for physical robots or unlock new avenues of rapid prototyping for creative fields. Of course, that requires that the model accurately simulate what you want. Genie 4 has several improvements that make its simulations more useful, and that’s partly due to Google’s updated Gemini models.
DeepMind says Genie 4 is better at simulating physics.
When you create a world in Genie 4, leverage Gemini 3.8 Flash as a guiding agent to break down objectives and evaluate each output frame. This helps keep the simulation going, allowing you to move through different environments without losing the original context. However, DeepMind notes that Genie 4’s worlds only remain consistent for a couple of minutes before forgetting how things started.
Like Genie 3, the new version supports changing parameters mid-stream. You can change the weather, add elements, or move the camera, and Gemini will help you direct the simulation with each update. This is similar to the way reasoning models generate additional internal cues to focus on the correct output tokens.