In any case, there was apparently enough structural data for the training to work.
Functional proteins
To test Pinal, the researchers asked it to design four very different proteins: a fluorescent protein, two enzymes, and one involved in a large multiprotein complex. Although the details vary somewhat from case to case, there was a similar process for each; Let’s take fluorescent protein as an example.
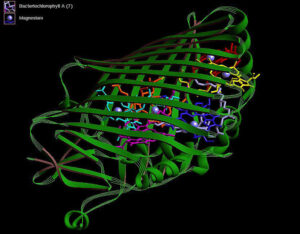
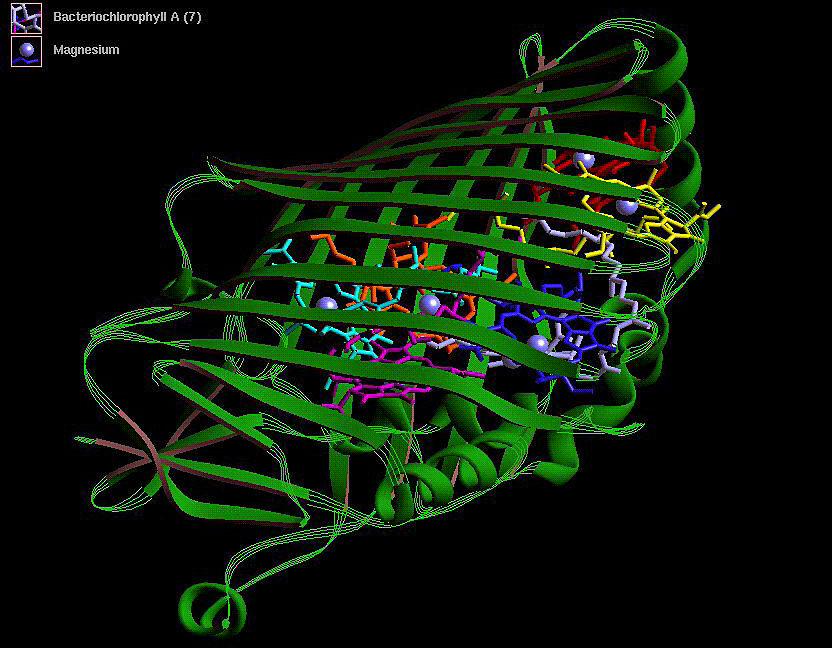
The classic example of a fluorescent protein that earned its discoverer a Nobel Prize is GFP, the green fluorescent protein. Pinal was asked to produce 50,000 proteins that could fluoresce like GFP. This extensive list was then filtered based on a number of criteria. First of all, the researchers rejected anything whose sequence looked like a known fluorescent protein. However, they settled on a few key features of GFP: the ability to form a barrel-like structure and the presence of a key amino acid that can be chemically modified to enable fluorescence.
In short, they wanted it to be a little similar to GFP in general, but not very similar in terms of the specific amino acid sequence. This filtering gave them a high-priority list of only 29 candidate proteins, all of which were made in E.coli. In total, one of them fluoresced.
All of the other examples were done similarly: start with a huge list, narrow it down computationally, and then test a few dozen designs, only a few of which would work.
It would be tempting to dismiss this as a shockingly low success rate. But keep in mind that many of the suggestions that would most likely work would be very similar to known GFP proteins and therefore would be discarded. The researchers also didn’t even bother testing whether things that didn’t form a GFP-like structure could work, so they may have rejected a wide range of alternative fluorescent proteins on that basis.